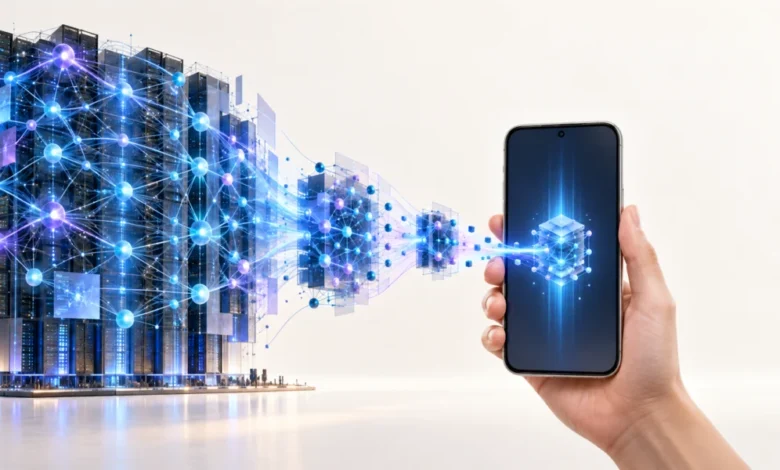
The artificial intelligence landscape has long been defined by an arms race of scale. For years, the industry consensus dictated that if a developer wanted a model with superior reasoning capabilities, the only path forward was to increase parameter counts, demand more GPU clusters, and consume vast amounts of energy. However, a quiet revolution is emerging from the labs of Caltech, where a startup named PrismML is proving that efficiency—not just sheer size—is the future of machine learning. By developing proprietary compression techniques that shrink complex models to a fraction of their original footprint, PrismML is positioning itself as a pivotal player in the transition from cloud-based AI to edge computing.
The Technical Foundation: Shrinking the Giants
At the heart of PrismML’s mission is a fundamental re-engineering of how large language models (LLMs) store knowledge. A standard LLM stores its "weights"—the numerical parameters that encode its intelligence—in 16-bit precision. This high-resolution storage is necessary for maintaining accuracy, but it is also what necessitates massive memory requirements.
PrismML has introduced a method known as "ternary weights." Instead of using 16-bit values, the company’s architecture reduces these weights to a simple three-value system: +1, -1, or 0. By drastically simplifying the mathematical representation of the model’s internal logic, the startup can achieve a memory reduction of 9x to 10x compared to original models.
The practical results of this innovation are best exemplified by the company’s latest release, Bonsai 2 27B. Based on the widely utilized Qwen3.8 27B open-source model from Alibaba, the Bonsai 2 iteration has been compressed to a mere 5.9 GB. This is a critical threshold; it allows a sophisticated reasoning engine to exist comfortably within the local memory of a standard personal computer and pushes the boundaries of what is possible on high-end smartphones.
A Chronology of Compression
PrismML’s rise has been swift, characterized by a series of aggressive development cycles and high-velocity releases that have caught the attention of both academic researchers and venture capitalists.
- Early 2026: The startup begins gaining traction following its seed funding round, which netted $22.25 million. Backed by Khosla Ventures, Cerberus Capital, and Caltech, the company secures its financial footing.
- March 2026: PrismML releases its first iteration of the Bonsai model. It achieves an impressive 95% performance parity with the original model, signaling that extreme compression does not necessarily equate to a total loss of "intelligence."
- Mid-2026: The adoption of these models surges. The company reports over 11 million downloads for its initial Bonsai release, with an additional 2.6 million downloads for its lighter variants, indicating a massive appetite for localized, portable AI.
- July 2026: Industry rumors circulate regarding potential collaborative discussions between PrismML and Apple. While CEO Babak Hassibi maintains a policy of silence regarding specific partnership inquiries, the speculation highlights the strategic importance of on-device AI for consumer electronics giants.
- August 2026: PrismML announces the release of Bonsai 2 27B, pushing the performance parity with the original Qwen model to 98%.
The Role of Academic Pedigree and Mentorship
The success of PrismML is deeply rooted in the ecosystem of Caltech and the influence of industry veterans. Led by Babak Hassibi, a professor at Caltech and a recognized authority in compression and signal processing, the startup leverages a deep academic background to solve complex mathematical problems that have previously stymied larger AI labs.
The company also benefits from the guidance of Ion Stoica, a luminary in the computing space. As a co-founder of Databricks and the director of the Berkeley Sky Computing Lab, Stoica brings a wealth of experience in scaling software infrastructure. His involvement underscores a broader trend: the convergence of academic research and commercial deployment. The Sky Computing Lab has already served as the incubator for significant projects such as Letta and SGLang, suggesting that PrismML is following a proven trajectory of high-impact technical output.
Beyond the Benchmarks: The Reality of Edge AI
While critics often point to the slight degradation in benchmark scores—the "2% gap" remaining between the compressed Bonsai 2 and its full-sized predecessor—Hassibi argues that such figures are largely academic. In practical, real-world application, the distinction between a 98% score and a 100% score is often imperceptible to the end user.
Furthermore, the environment in which an LLM operates—the "harness" or the software layer surrounding the model—often plays a larger role in final accuracy than the weight precision itself. By focusing on the weights, PrismML is optimizing the efficiency of the core engine, allowing the surrounding application layer to handle the complexities of task-specific reasoning.
Looking ahead, the startup is shifting its focus toward larger models. Hassibi suggests that as the base models grow into the hundreds of billions of parameters, the potential for compression actually increases. "There is more room to be able to compress them without losing the intelligence," he explained. This suggests that the future of AI will not be limited to small, specialized models, but will eventually include high-performance, compressed versions of the most powerful models currently available.
The Implications for Privacy and Accessibility
The shift toward on-device AI carries profound implications for data privacy and digital infrastructure. Currently, most advanced AI interactions require the transmission of user data to the cloud, where massive server farms process requests and return answers. This model creates inherent privacy risks and latency issues.
Ion Stoica views the work of PrismML as a democratization of high-end intelligence. "You are going to have intelligence at your fingertips, and it’s going to be free because it’s going to run on the device you already bought," Stoica noted. By shifting the processing load to the user’s hardware, PrismML enables a future where AI is "local-first." This eliminates the need for constant cloud connectivity and ensures that sensitive user data remains on the device, significantly reducing the attack surface for data breaches.
Moreover, the economic impact of this technology cannot be understated. By reducing the hardware requirements for high-performing AI, companies can lower the cost of deployment. Developers will no longer be beholden to the prohibitively expensive cost of renting cloud GPU time, effectively lowering the barrier to entry for smaller startups and independent developers to build and deploy complex AI applications.
Future Outlook and Market Competition
PrismML is not operating in a vacuum. The race to achieve the most efficient compression is heating up, with firms like Multiverse Computing securing significant capital to pursue similar goals. However, PrismML’s focus on maintaining high performance while shrinking models by nearly an order of magnitude provides them with a distinct competitive advantage.
The company’s ability to iterate rapidly—as evidenced by the leap from 95% to 98% performance parity in just a few months—suggests that they are still in the early stages of their development curve. If they continue on this path, the "100% parity" milestone may be achieved sooner than many analysts expect.
Whether through eventual integration into mobile operating systems or adoption by enterprise software platforms, the technology developed by PrismML is set to define the next phase of the AI evolution. As the industry moves away from the "bigger is always better" mentality, the ability to pack maximum reasoning power into the smallest possible space will become the ultimate metric of success. The transition is underway, and if the early adoption numbers are any indication, the market is more than ready for AI that lives on the device, rather than in the cloud.